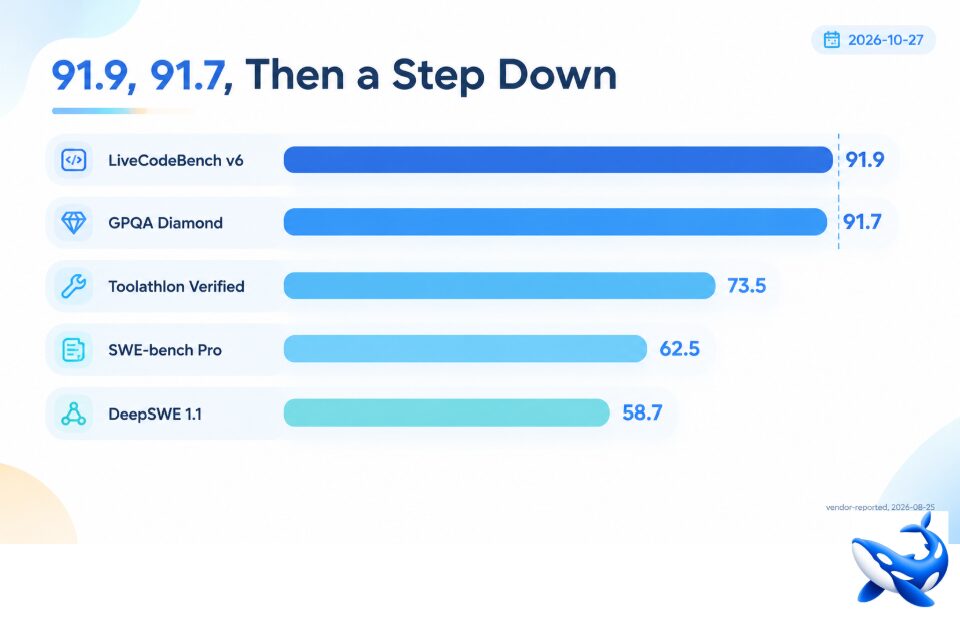
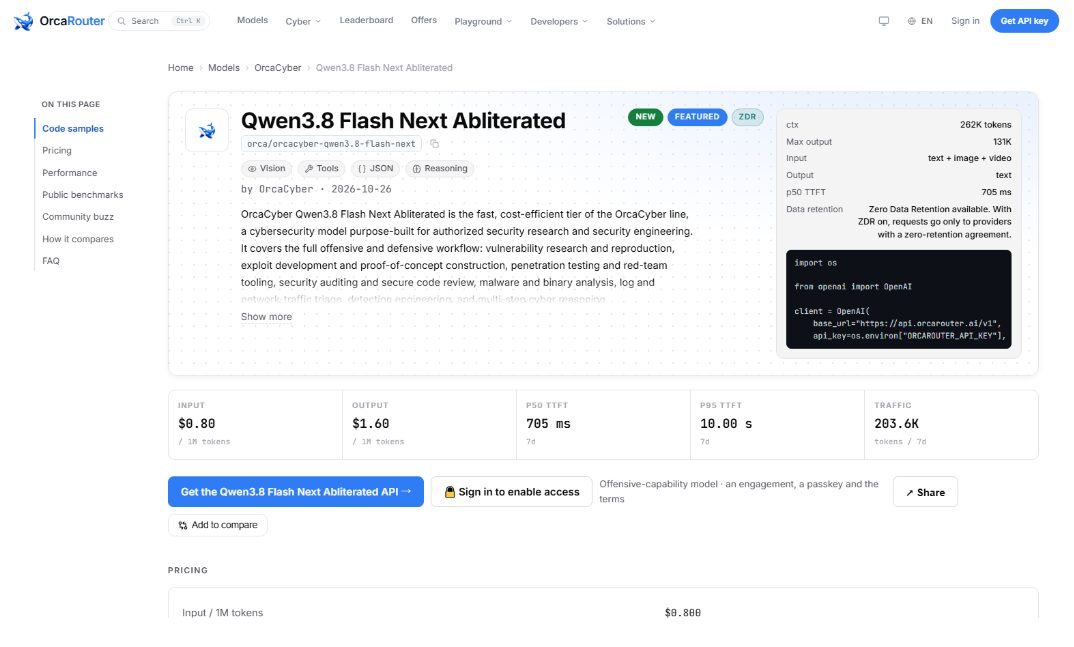
Through OrcaRouter the tuned card and its base model share a key, which makes the OrcaCyber Qwen3.8 Flash Next benchmark table easy to check against the model it was built from. The five published rows have a shape that is more informative than any one of them: two at ninety-one, one at seventy-three, and two in the low sixties and high fifties [VENDOR]. That is not a plateau — it is a cliff, and where the cliff starts tells you what the tuning preserved and what it did not.
Here is the table as published.
| Benchmark | Score | What it asks |
| LiveCodeBench v6 | 91.9 | Competitive-programming problems, contamination-controlled |
| GPQA Diamond | 91.7 | Graduate-level science questions |
| Toolathlon Verified | 73.5 | Real-world tool use across many APIs |
| SWE-bench Pro | 62.5 | Resolving real software issues |
| DeepSWE 1.1 | 58.7 | Software-engineering tasks, agentic |
All five are OrcaCyber’s own evaluations, dated 2026-08-25 — two months before the card shipped, a detail worth returning to [VENDOR].
The two ninety-ones are not the same achievement
LiveCodeBench v6 asks a model to solve programming problems, with a versioned, contamination-controlled problem set. Ninety-one point nine means the model writes correct algorithmic code at a rate that would have been frontier-level a generation ago.
GPQA Diamond asks graduate-level physics, chemistry and biology questions written to be search-resistant. Ninety-one point seven means the model reasons well outside code.
The two numbers being nearly identical is the interesting part — it says this base is not a narrow coding specialist. Alibaba’s Qwen line has been strong on both for a while, and a refusal-free tune that leaves both intact has not damaged the base’s reasoning.
For a security workflow that matters more than it sounds. Half of vulnerability work is code reading; the other half is understanding what a system does, which is a science-and-systems reasoning problem. A card that kept both is usable for both halves.
Where the cliff starts
The drop from 91.7 to 73.5 is eighteen points, and it happens exactly at the boundary between answering questions and operating tools.
Toolathlon Verified puts a model in front of many real APIs and asks it to complete tasks end to end. Seventy-three and a half is a working score — it means the model usually completes the sequence — but it is a different kind of number from 91.9. One measures whether the model can produce a correct answer; the other measures whether it can produce a correct sequence of actions without losing the thread.
Then SWE-bench Pro at 62.5 and DeepSWE 1.1 at 58.7 describe the hardest thing on the list: changing a real codebase correctly. Roughly six in ten tasks come back right. That is the row that predicts what happens when you hand the model a remediation backlog rather than a question.
What the shape buys you
Read as a profile, the five rows say: strong at reasoning, competent at tool use, ordinary at engineering delivery. That is a coherent product, and it matches the card’s stated purpose — vulnerability research, exploit development support, triage, detection engineering — where most of the work is understanding and a smaller share is patching.
The corresponding workflow is:
- Use it to read and explain: a stack trace, a diff, a protocol spec, a CVE writeup. The 91s are the evidence.
- Use it to drive tools with validation around each step: 73.5 is good enough for an agent that checks its own results, not for one that runs unattended overnight.
- Do not assume the patch it writes applies cleanly: 62.5 and 58.7 say roughly four in ten attempts will need a human.
The provenance detail
The evaluation date is 2026-08-25, and the card was released 2026-10-26. The rows therefore describe the tuned checkpoint before it was served, not a measurement taken afterwards.
That is normal for a vendor card and it is not a criticism. It does mean the numbers cannot capture anything that changed in serving — and on this card there is nothing else to capture, because its production traffic is measured in thousands of tokens rather than billions [OURS].
A reader should treat the five rows as the vendor’s claim about the tuning, and nothing more. What they are good for is setting expectations before you test, not replacing the test.
What the table does not include
Three omissions are worth naming, because each corresponds to something a security team will need.
No security-specific harness. There is no CyberGym, no SEC-Bench Pro, no CVE-Bench row here. The siblings publish those; this card publishes general capability instead. Whether that is because the numbers are unflattering or because the tuning was aimed at code and science reasoning is unknowable from the page.
No long-context row. The card ships a 262,144-token window and no measurement exercises it. Given that the window is a quarter of the base model’s, that omission is the most interesting one on the list.
No served-endpoint evidence. Benchmark rows are harness measurements; latency, throughput and error rate are separate, and this card has no usable production sample yet [OURS].
How to test the two ends yourself
Two probes cover the range, and both use your own material.
For the 91s: give the model a vulnerability you already understand, described in a paragraph, and ask what class it belongs to and what the fix looks like. A model with intact reasoning answers at the level of the class; a model that has lost it pattern-matches a CVE name.
For the 60s: give it a real issue from your tracker with the failing test and ask for the patch. Apply it. Count how many apply cleanly and how many pass. Ten cases will tell you whether 62.5 is your number or an optimistic one.
Neither probe needs a harness. Both produce a number you can act on, and together they cost less than an hour of inference.
The takeaway
Two rows at ninety-one say the base model’s reasoning survived the tuning. Three rows between fifty-eight and seventy-four say the delivery half is ordinary — and ordinary at sixty-two is what “roughly four in ten need a human” feels like in practice.
Buy it for reading, explaining and tool-driven research with validation. Test the patch path before you route production remediation through it.
If you keep one thing from the table, keep the shape: two rows in the nineties and three below seventy-five. That is a description of a generalist, and a generalist is the right instrument for work that does not announce which kind of problem you are about to hand it.
Sourcing note: all five benchmark rows are OrcaCyber’s own claims, evaluated 2026-08-25 and published on the model page; none has been independently reproduced [VENDOR]. Pricing and context figures are OrcaRouter catalogue data, checked 2026-10-27 [OURS]. No latency, throughput or reliability figure is quoted, because the card’s production sample is too small to support one [OURS].